Tural Hajiyev

Frontend Engineer

How to Rewrite Array Methods — map, filter, reduce, flatMap From Scratch

Sep 2, 2026

How to Rewrite Array Methods — map, filter, reduce, flatMap From Scratch

While preparing for interviews, I found out that one of the "hot-potato" topics of javascript interviews is, implementing map, reduce, filter flatMap methods from scratch. First it sounds easy to do, as JS developer we almost everyday using it but from the first line I got stuck. I even forgot how to add a method to Array, because I don't remember when last time I used prototype. More or less, this is what I relearned while getting it right.

map method

Map function of Array has 2 parameters - callbackFn and thisArg.

Callback function is easy, as we always use it. For example,

const items = [1,2,3,4,5] const newItems = items.map(item => item * 2)

It's the must-have parameter, but I don't remember any time I used thisArg.

thisArg is used as this when executing callbackFn. For example, let's say we have following code:

const calculator = { multiplier: 10, multiply(x) { return x * this.multiplier; } }; const numbers = [1, 2, 3]; const result = numbers.map(calculator.multiply);

I would expect this.multiplier will be undefined, and the result will be [NaN, NaN, NaN]. But if you ask me how to solve it, I couldn't answer. That's when thisArg is useful actually. If we pass calculator as thisArg to map function, the result will change:

// previous object definition const result2 = numbers.map(calculator.multiply, calculator);

This time, the result will be [10,20,30] instead of multiple NaN.

thisArg is ready, now it's time to think about callback function. It also receives multiple arguments: element, index, array

Now we have the full setup to create our own map function.

First we need to define the function. we can do that by adding function to Array.prototype:

Array.prototype.myMap = function(callback, thisArg) {}

So it's the background to work with the function. Inside, we can define empty array, we can iterate over initial array, and we can call the callback function we have with call function. Why call function? It will help us to define the environment to call the callback. First argument of call function is this environment, and the remaining ones are arguments we want to pass to the function.

let array = []; for (let i = 0; i < this.length; i++) { array.push(callback.call(thisArg, this[i], i, this)) }

Here, thisArg is the environment we want to the call the function. (for example, calculator object). this[i] is the element we access currently. i is the index, and this is the original array.

If we combine it with the previous code, the result will be:

Array.prototype.myMap = function (callback, thisArg) { let arr = []; for (let i = 0; i < this.length; i++) { arr.push(callback.call(thisArg, this[i], i, this)); } return arr; };

It will work. Partially. While working on it, I learned something new related to arrays. map function should return the array with the same length. Array can have multiple values like number, string, undefined, null, but it can also have holes. For example, following array is valid:

const arrayWithHole = [1, , 3]

If we call this array with our method for example to multiply with 2, the hole will become NaN. If we don't do anything, it will be undefined. Ideally, we need to keep it as a hole, because we didn't set any value. For that, we need to catch if it's the hole, and skip calling callback function. It can be done by having in operator:

if (i in this) // call callback // move to the next element

The most final code will be:

Array.prototype.myMap = function(callback, thisArg) { if (typeof callback !== 'function') throw new TypeError(`${callback} is not a function`); const result = []; for (let i = 0; i < this.length; i++) { if (i in this) { // skip holes in sparse arrays result.push(callback.call(thisArg, this[i], i, this)); } } return result; };

filter method

Filter function has the same shape as map. The main difference is we conditionally pushing to the result array, which means length of initial array and output array can be different.

Array.prototype.myFilter = function(callback, thisArg) { if (typeof callback !== 'function') throw new TypeError(`${callback} is not a function`); const result = []; for (let i = 0; i < this.length; i++) { if (i in this && callback.call(thisArg, this[i], i, this)) { result.push(this[i]); } } return result; };

Here, if it's not a hole and callback.call(...) returns true, we add the element to the result array. Otherwise we just skip it.

reduce function

Here is the definition of reduce method in MDN:

The reduce() method of Array instances executes a user-supplied "reducer" callback function on each element of the array, in order, passing in the return value from the calculation on the preceding element. The final result of running the reducer across all elements of the array is a single value.

It's coming with 2 arguments, first one is callbackFn and the second one is initialValue we want to start with.

Also callbackFn is coming with accumulator (The value resulting from the previous call to callbackFn), currentValue (The value of the current element), currentIndex (The index position of currentValue in the array) and array (The array reduce() was called upon)

So main idea is, first we check if initialValue is provided or not. Based on that, we find initial value, and initial index. If provided it's easy, otherwise we need to find first valid element to start to the accumulator.

let acc; let startIndex; if (arguments.length >= 2) { acc = initialValue; startIndex = 0; } else { // find first non-hole element to use as initial acc let i = 0; while (i < this.length && !(i in this)) i++; acc = this[i]; startIndex = i + 1; }

After having valid accumulator and startingIndex, we can iterate over array, and call callback function:

for (let i = startIndex; i < this.length; i++) { if (i in this) { acc = callback(acc, this[i], i, this); } }

and the final code will be:

Array.prototype.myReduce = function(callback, initialValue) { if (typeof callback !== 'function') throw new TypeError(`${callback} is not a function`); if (this.length === 0 && arguments.length < 2) { throw new TypeError('Reduce of empty array with no initial value'); } let acc; let startIndex; if (arguments.length >= 2) { acc = initialValue; startIndex = 0; } else { // find first non-hole element to use as initial acc let i = 0; while (i < this.length && !(i in this)) i++; acc = this[i]; startIndex = i + 1; } for (let i = startIndex; i < this.length; i++) { if (i in this) { acc = callback(acc, this[i], i, this); } } return acc; };

flatMap method

flatMap is map followed by a flatten of depth 1. We can use the above code slightly modified, just add a narrowing for Array type. If it's an array, we need to destruct it, otherwise we can push it as it's:

Array.prototype.myFlatMap = function(callback, thisArg) { const result = []; for (let i = 0; i < this.length; i++) { if (i in this) { const mapped = callback.call(thisArg, this[i], i, this); if (Array.isArray(mapped)) { result.push(...mapped); } else { result.push(mapped); } } } return result; };
Jun 18, 2026

React Project Folder Structure — Patterns for Scalable Frontend Apps

When React was first released, it became popular with the type-based folder structure. Later, as bigger projects were created, the feature-based folder structure started to become popular. Both structures have their own benefits, and making the right choice fully depends on the project's scope and needs.

While writing this article, I also wanted to include Atomic Design, but then I realized it's not really a folder structure. It's a great example of how UI libraries can be organized, but the biggest blind spot of Atomic Design is that it wasn't designed for data or logic. It says nothing about where API calls, hooks, or business logic go. Atomic Design was created purely for UI composition, not for handling data or application logic. It can be used together with all folder structures, but alone it can't help to create a full frontend application.

To make things easy to understand, I will mention an ERP application with contacts, trade, finance, and hr modules. This application will be mentioned in multiple places.

Type-based folder structure

Here's a common example of what a type-based folder structure looks like:

src/ components/ hooks/ services/ utils/ pages/

Here, the idea is to have a folder for each type (component, hook, etc.) and store them together. This structure has its own advantages and disadvantages.

Advantages

This structure has been around since the early days of React and remains familiar to most developers today. Many small and mid sized projects still use it, making it easy for new team members to get started without much explanation. Since it's so common, you don't need to spend time debating folder structure upfront—just group files by their "type" (component, hook, etc.) and go.

Initially, all applications start simple, so it's a smart move to start with this structure and move to a more complex one later, instead of struggling with a complex folder structure when you have only a few components and hooks.

Disadvantages

Because the relationships between files aren't clear in this structure (for example, a component in components might use another component or a custom hook from somewhere else), it becomes pretty difficult to make changes to a single feature.

Imagine the company decides the hr module should become its own standalone application. Trying to delete that module or move it to a new GitHub repo quickly turns into a headache, since there's no clear way to know which files belong to HR, what its dependencies are, or where its boundaries end. Sure, you could try to prefix everything with HR (HRLandingPage.tsx, HRPeople.tsx) to keep things together, but once you break this naming rule anywhere, or if you rely on a shared function (like a usePeople.tsx hook), it all gets messy and hard to untangle.

Also, it's worth mentioning that if you decide to define boundaries by using prefixes like HR, Finance, or Contacts, after a while you will see really ugly file names in the repo. HRPayrollTableWithEditModal.tsx is not a good name, and you will not be happy to see it every time.

Additionally, as files for a single feature end up scattered between different folders, you often have to jump around the codebase to trace how everything connects. For people working on the project daily, this back-and-forth becomes second nature.

But for new team members, or if you step away from the project and return later, it's much harder to piece together how components, hooks, and other files relate. In /components with over 100 files or in the /hooks folder with 25 files, it's easy to get lost, even if you knew the project well before.

Feature-based folder structure

src/ features/ hr/ components/ hooks/ api/ finance/ components/ hooks/ api/ shared/ components/ hooks/ api/

With this structure, each feature has its own folder to live in. Additionally, there is a shared folder to store common code and services used across multiple modules.

Firstly, this structure makes it easy to understand the business domain and manage code, because all files related to a feature are grouped together. If you hire a new team member and they are required to work in the finance module, they don't need to check the hr module. (It's not always true, but it works in certain cases. My point is it's easier to work within a feature's folder without jumping around the project.) Also, this benefit makes it easier to delete a feature or promote it to a new application, which was a nightmare with a type-based folder structure.

Secondly, as the project grows, new features don't clutter up unrelated areas. If you start to work on an "Orders" module, it will be fully isolated, and you won't need to worry about your code mixing with HR or Finance.

Finally, shared code lives in a clear location, and features are less likely to depend on each other's internals. It's not 100% true, but works in most cases. I will mention in the next paragraph that sometimes one module needs to consume another module's functionality, and that's when things can get messy.

Disadvantages

As mentioned in the previous paragraph, sometimes features can depend on each other's internals. Imagine there is a trade module, and after you create a trade invoice, you need to call a function from the finance module to make the payment. This logic breaks the motivation behind the feature-based structure, as one feature depends on another one, and they are not isolated anymore. You can think to move this functionality to the shared folder, but then a functionality related to finance will sit in the shared folder, instead of finance. I would say it's one of the main constraints of the feature-based structure in large scale applications.

Secondly, if not managed carefully, some logic might get duplicated across feature folders. Especially at rush times or with short deadlines, when code reviews get skipped, you can easily find some functionality (utils/disableScroll.tsx) defined in two modules instead of the shared folder.

Finally, if you have work which covers all components or all hooks, this structure is less predictable by type. It means if you need to check all components, you need to visit each feature's components folder instead of having a single components folder.

Feature-based folder structure is ideal for most medium sized projects. For large projects, sometimes it raises questions as mentioned before, like should features only use code in the shared folder, or is it okay for one feature to directly import code from another? What if the trade module has a small feature that after a trade operation, it's required to call a finance operation? Without clear rules, you can accidentally create tangled dependencies between features and suddenly lose the main benefit this structure brings. In addition, over time, a single feature folder can become bloated as new components, hooks, and logic are added. It's not always obvious when a feature has grown too large and should be split up into smaller sub-features or reorganized for clarity.

What about Feature-Sliced Design (FSD)?

You might have heard about Feature-Sliced Design (FSD). It's a relatively new, layered architectural approach that's gaining popularity for organizing large-scale frontends. FSD introduces concepts like "layers" (app, pages, widgets, features, entities, shared) and "slices" for domain grouping, and enforces clear, strict boundaries between them.

I haven't used Feature-Sliced Design (FSD) in a production project myself yet. I'm still learning about it and exploring how it works.

Apr 24, 2026

GraphQL vs REST API — Which one to choose?

A REST API is like a restaurant with a set of fixed combo menus. You can order Menu A, which comes with a burger, fries, and a cola — but you can't swap the fries for a salad. GraphQL, on the other hand, sells you everything à la carte, so you build your own plate exactly the way you want it.

Say you're building an ERP application and it uses a REST API to make requests for different modules. Different API endpoints help get data related to relations, trade operations, and finance data. For example, the backend team sets up /relations and wires up each endpoint:

GET /api/v1/relations/ GET /api/v1/relations/[relation-id] POST /api/v1/relations PUT /api/v1/relations DELETE /api/v1/relations

In REST APIs, the server shapes every response. You get fixed endpoints like (/relations/1, /relations/1/trade-operations), and each returns a defined structure.

Over-Fetching and Needing Backend Changes

The GET /api/v1/relations endpoint returns a large dataset for each relation. For example, the data might look like this:

[ { "id": "1725", "fullName": "Michael Scott", "companyName": "Dunder Mifflin", "date": "2024-01-01", "address": "1725 Slough Avenue, Scranton, PA", "phone": "555-2323", "notes": "World's Best Boss" // ...many other fields }, { "id": "1726", "fullName": "Pam Beesly", "companyName": "Dunder Mifflin", "date": "2024-01-10", "address": "1727 Slough Avenue, Scranton, PA", "phone": "555-4545", "notes": "Receptionist" // ...many other fields } ]

For the relations page, we need this data. A new task comes in, and it's required to show relations on the dashboard in compact form. For the dashboard, you only need fullName, companyName, and date. Calling GET /api/v1/relations brings back all fields—more than you want. That's over-fetching.

With REST API, there are two common ways to improve it. Either a new endpoint can be introduced with the compact data,

GET /api/v1/relations/mini-dashboard

or filters can be added, which can be used to get only the necessary fields:

GET /api/v1/relations?fields=fullName,companyName,date

Both implementations require backend changes. It's required to add a new endpoint, or update the existing one. Over time, endpoints may drift from what the frontend needs.

Over-fetching isn't just a read concern. If you POST a new relation and want only the id and fullName back, you still might get the entire object:

{ "id": "1725", "fullName": "Michael Scott", "companyName": "Dunder Mifflin", "date": "2024-01-01", "address": "1725 Slough Avenue, Scranton, PA", "phone": "555-2323", "notes": "World's Best Boss" // many other fields }

Getting a bunch of unnecessary data back, with no way to avoid it, is called over-fetching.

GraphQL uses a different model. There's one endpoint (/graphql). The frontend picks the fields it wants, regardless of scenario.

Instead of /api/v1/relations always returning the same thing, a GraphQL query can be as specific as the client likes:

query { relations { fullName companyName date } }

GraphQL lets the client decide which fields to fetch—from a single endpoint (/graphql).

  1. No over-fetching anymore, and frontend gets the fields it asks for.
  2. No backend change needed for small tweaks. Need to add a date field? Only need to include it in the query (as long as that field's in the schema).

Multiple Requests and Chatty APIs

REST usually means making several calls to build a single page. A dashboard, for example, might need:

  • GET /api/v1/relations
  • GET /api/v1/relations/:id/trade-operations
  • GET /api/v1/relations/:id/financial-operations

Each call adds to network overhead. If the data is nested or related, you have to keep stacking requests to get a complete view.

With GraphQL, the client can ask for everything at once—including nested and related records:

query DashboardRelations { relations { id name tradeOperations { id date financialOperations { id amount } } } }

It's easy to avoid over-fetching, and there's no need to merge and manage results from multiple REST calls.

Type Safety

REST returns generic JSON. On the frontend, developers can write TypeScript interfaces to match the responses. If the backend changes a field (or its name), types can get out of sync easily. It's easy to miss these changes, and your app and API quickly drift apart.

You often handcraft interfaces:

interface FinancialOperation { id: number; amount: number; } interface TradeOperation { id: number; date: string; financialOperations: FinancialOperation[]; } interface Relation { id: number; name: string; tradeOperations: TradeOperation[]; }

If the backend renames a field (say, amount becomes value), in REST you need to find and update every related TypeScript interface throughout your app. As your app grows, this gets more painful.

With GraphQL, the schema is typed, and you can generate your TypeScript types straight from it. When the schema changes, just rerun codegen, and your frontend types stay in sync. No guesswork, no more hand-maintained interfaces.

Cache Sync

With REST, you typically have to refetch big lists (inefficient), or manually patch cached entries (fragile and messy):

const mutation = useMutation(updatePost, { onSuccess: () => { queryClient.invalidateQueries(["posts"]); // refetch all posts }, });

With a normalized GraphQL client like Apollo or Relay, data is cached by unique ID. When an object is updated, all parts of the UI using that data are updated automatically. No need to refetch lists or manually update the cache. (Note that this caching behavior comes from the client library, not GraphQL itself.)

When To Use GraphQL or REST

It depends. If the data is deeply nested, and you have multiple clients with different data needs, that's when GraphQL shines. Or, if there are over-fetching pains in many places, GraphQL is a great tool to use. One schema acts as the source of truth. Frontend teams can move faster without constantly asking for changes from backend tweaks.

If the API is simple—just a few resources, basic CRUD, and maybe file uploads, REST is often best. Simple is good for files, webhooks, and integrations that don't need deep flexibility.

In practice, teams mix both: GraphQL for the main app UI, REST for jobs like file uploads, authentication, webhook handlers, or talking to legacy systems. The setup isn't always pretty, but it works and scales as needs evolve.

Mar 4, 2026

Monolith, Monorepo, or Microfrontends?

Discussions about frontend architecture often include suggestions to use microfrontends. But when I look for strong reasons behind these recommendations, they rarely hold up for most teams.

Here's my core takeaway:

Microfrontends are designed to let completely independent teams deploy their features separately from each other. This only makes sense if you are at a large company with distinct, siloed teams. Most organizations don't need this level of separation. The popularity of microfrontends has more to do with the appeal of new trends than with solving everyday problems.

A lot of confusion comes from treating these ideas as a single decision, when in reality they're separate:

  1. Where does your code live? One repo or multiple (monorepo vs polyrepo)?
  2. How is code structured inside the repo? Is everything together, or split into packages (single package vs workspaces)?
  3. How does it run in the browser? Is there one deployed build, or several independently deployed builds combined at runtime (monolith vs microfrontend)?

You can have a monorepo and still ship a single monolith. You can break a monorepo into workspace packages while keeping one deployable artifact. Microfrontends only address the third point, which is about how your code ships and runs—not where the source lives.

The main promise of microfrontends is this: Teams can deploy to production independently.

That's basically it. In practice, it means scenarios like:

  • Team A can release code on Tuesday afternoon, Team B can release Thursday morning. One team's work doesn't block the other. A buggy deployment in one module doesn't crash other unrelated modules on the same page.
  • Teams can set their own testing or release cadence, as long as everyone agrees on integration boundaries.
  • Ownership lines are clearer and each team handles its own CI/CD, on-call, and maintenance.

Q: If my code is in different repos or npm packages, do I have microfrontends?

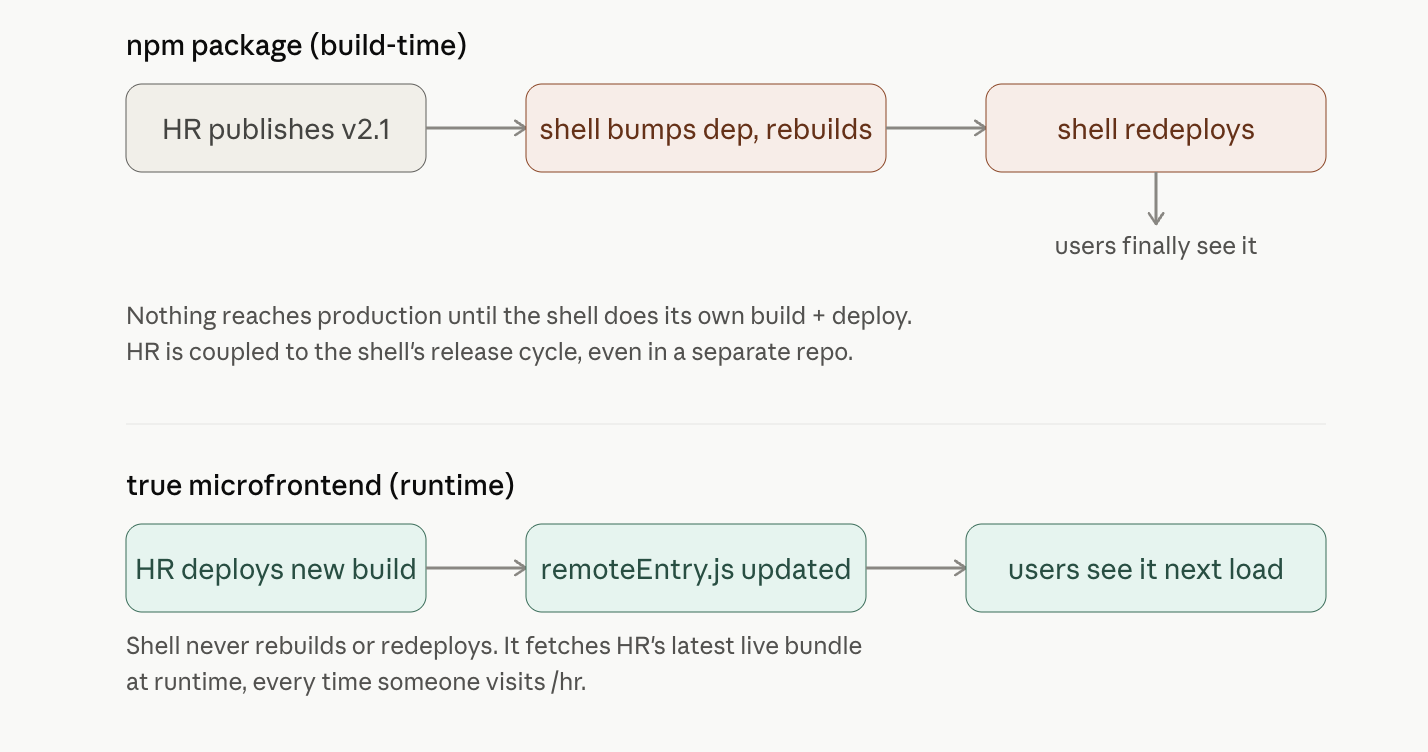
A: Not exactly. If you publish to npm and your shell app installs other packages from there, you're still combining everything at build time, not at runtime. You don't get real independent deployment. Even with code in different repos, deployments are still tied together and require coordination. Here is the difference visually:

Diagram: NPM package vs Microfrontend deployment

True independence comes with challenges.

One big challenge is loading React and React DOM as true singletons across all modules. Version mismatches won't always throw build errors; problems may only show up at runtime in production. Each module needs its own build pipeline, deployment environment, and a robust system for sharing and versioning the manifest that lets the shell discover them.

Local development also gets trickier. You may have to juggle multiple dev servers, or mock modules you aren't actively working on, just to get things running.

Tracing problems across runtime boundaries is more complex than tracing through regular function calls. And optimizing performance is less straightforward since the bundler can't see or deduplicate all code in one place.

Q: Do your HR, Finance, and Trade teams actually need to deploy independently whenever they want?

A: If each team has its own roadmap, works in isolation, and release coordination is a real, recurring pain, then microfrontends can add value. But if there's really just one team, or everyone ships together by default, microfrontends introduce a lot of complexity for almost no gain.

Oct 5, 2025

Fancy TypeScript Things I Use Every Day (But Didn't Know Their Names)

Static vs dynamic typing

JavaScript is dynamically typed, TypeScript is statically typed. Day to day, it means, in JavaScript, a variable's type is a runtime fact. The engine doesn't know or care what user is until the code actually runs and it looks at the value sitting in memory.

var user = { name: "Tural" }; user = 42; // Even if there is a police, it's totally legal

TypeScript moves that check earlier, to the moment you write the code, not the moment the engine runs it. The compiler builds a model of what every variable should be, and if you try to violate that model, it complains before your code ever executes.

var user = { name: "Dana" }; user = 42; // Type 'number' is not assignable to type '{name: string}'

These types do not exist at runtime. They are erased during compilation, as we generate .js code from .ts code to run the app. The browser or Node environment has never seen a type or an interface in its life. It can't save us from a bad API response or a null value that we defined as number, because TypeScript is reasoning about the code without running it.

Type narrowing

Narrowing is TypeScript watching your control flow and shrinking a type based on what you have already checked. It's the reason this doesn't work:

function printLength(value: string | number) { console.log(value.toFixed(2)); }

and this works:

function printLength(value: string | number) { if (typeof value === "string") { console.log(value.length); // TS knows it's a string here } else { console.log(value.toFixed(2)); // and a number here } }

In the if block, we don't need to say TypeScript value is a string. It figured that out on its own from the typeof check. That's narrowing. It works with typeof, instanceof, in, truthiness checks, equality checks against literals.

Narrowing lets TypeScript discriminate between variants of a union:

type Shape = | { kind: "circle"; radius: number } | { kind: "square"; side: number }; function area(shape: Shape) { if (shape.kind === "circle") { return Math.PI * shape.radius ** 2; // radius exists, guaranteed } return shape.side ** 2; // side exists here instead }

That kind field is doing all the work. Because each variant has its own literal type for kind, checking it lets TypeScript figure out exactly which shape of object you are holding at each branch. In the TypeScript world, it is also known as a tagged union.

Control flow analysis

TypeScript doesn't just look at each line in isolation, it keeps track of how your code flows, updating what it knows about each variable along the way. This is called control flow analysis.

Because of that, TypeScript can spot when certain conditions are no longer possible, which lets you write safer, more expressive code. For example:

function getUser(id: string | null) { if (!id) { return null; } // TypeScript knows id can't be null here return fetchUser(id); }

Here, since we return early when id is null, TypeScript understands that by the time we reach fetchUser(id), id must be a string, not null.

But control flow analysis really shines when dealing with union types and exhaustive checks. If you forget to handle all possible cases in a switch, TypeScript can catch it at compile time:

type Status = "loading" | "success" | "error"; function getMessage(status: Status) { switch (status) { case "loading": return "Loading..."; case "success": return "It worked!"; // What if we forget "error"? default: // TypeScript can flag this as an unhandled case. // To make this safer: const _exhaustiveCheck: never = status; return _exhaustiveCheck; } }

If you later add another variant (like "idle") to Status, TypeScript will warn you anywhere the type needs to be updated.

Contextual typing

This is something all of us using every day, just don't know its name. Contextual typing is when TypeScript infers a type for something based on where it's being used, rather than from the expression itself.

window.addEventListener("click", (event) => { console.log(event.button); // event is inferred as MouseEvent, not `any` });

In this example, we never define type for event. TypeScript looked at the signature of addEventListener, saw that click event maps to a MouseEvent handler, and typed the callback's parameter accordingly. Same story with array methods:

const prices = [10, 25, 40]; const doubled = prices.map((price) => price * 2); // price: number, inferred

price is contextually typed as number, because TypeScript knows that prices is number[] andmap's callback parameter matches the array's element type.

Apr 10, 2025

How a Web Page Loads HTML, CSS, and JS Content

HTML document is the first thing the browser needs before anything can be shown. It sends a request to the server, and the server responds with an HTML file. This file is the skeleton of everything. Without it, there's nothing to parse, style, or render. Every other resource (CSS, JavaScript, images, fonts) is discovered through this HTML, so it has to arrive first.

Once the HTML starts arriving, the browser doesn't wait for the whole file and it begins parsing immediately, streaming through the markup from top to bottom, converting tags into a tree of nodes called the DOM (Document Object Model).

This top-to-bottom order matters a lot. The position of a <link> or <script> tag in the document directly affects when and how the browser handles it.

When the parser encounters a CSS file, it doesn't stop building the DOM. CSS doesn't block HTML parsing.

CSS file only blocks rendering. The browser won't paint anything to the screen until it knows the styles, because painting unstyled content and then restyling it would cause an ugly flash and wasted work. The CSS file is fetched, parsed into the CSSOM (CSS Object Model), and once both the DOM and CSSOM are ready, they combine into the render tree.

CSS doesn’t block the HTML parser, but it does block rendering.

Hitting a <script> Tag

There are 2 pathways here:

  • Inline <script>: already in the HTML, no network request needed.
  • External <script src="...">: the browser has to fetch it.

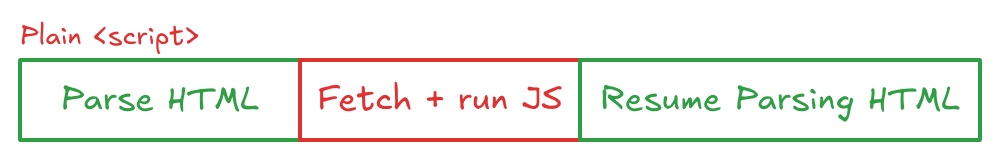
Script tags block the HTML parser by default. The browser's HTML parser reads your page top to bottom, building the DOM as it goes. When it hits a <script> tag with no attributes, it has to:

  1. Stop parsing HTML.
  2. Fetch the script (if external).
  3. Run the JS engine on it, fully, top to bottom.
  4. Only then resume parsing the rest of the HTML.

Always put your <script> tags at the bottom of <body> — it's classic advice everyone has heard at least once. Let the page's visible content parse first; otherwise, all content will be blocked.

Plain <script>: blocks HTML parsing entirely while it fetches and runs.

async and defer exist specifically to avoid this blocking.

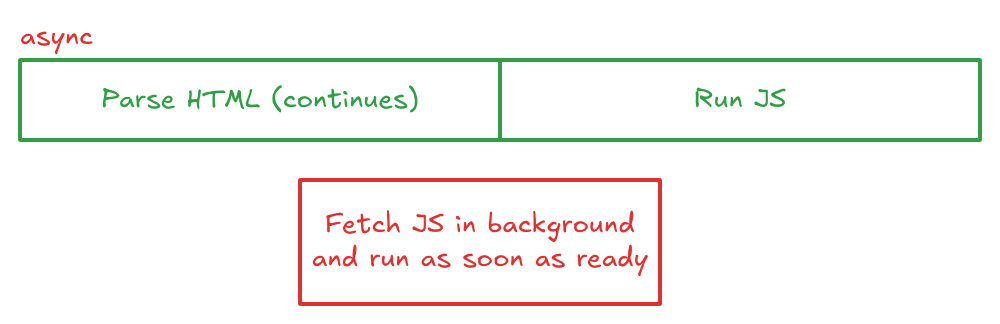
async fetches in parallel with HTML parsing, but runs the moment it's ready. It pauses parsing whenever that happens, in whatever order scripts finish downloading.

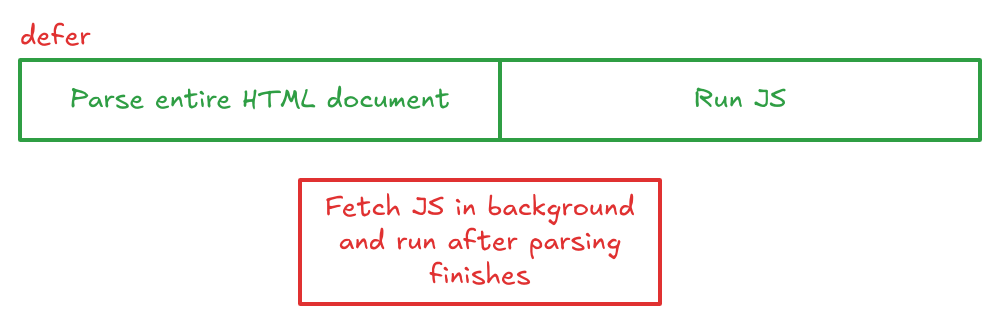
defer fetches in parallel too, but always waits until the HTML document is fully parsed, and runs multiple deferred scripts in their original order.

Once the DOM (structure) and CSSOM (styles) both exist, the browser merges them into the render tree.

The browser then calculates the exact size and position of every visible element on the page, which is called layout or reflow. It figures out, in pixels, where the box for each element sits relative to the viewport and its neighbors.

After layout (reflow) but before painting, the browser runs "layout effects" like React's useLayoutEffect. This lets you measure or change the DOM right before anything is shown to the user.

With the positioning and any layout effects settled, the browser proceeds to the paint phase by filling in all the pixels: text, colors, borders, shadows, and images.

After the browser paints the screen, React runs useEffect. This is good for things like data fetching or logging, since it happens after the user already sees the changes.